OCR Consensus: EasyOCR and Qwen3-VL Agree on 5 of 444 Pages
I diffed the EasyOCR and Qwen3-VL transcriptions of 444 Soviet cookbook pages against each other, and the two engines produced character-for-character identical text on only 5 pages. All 5 are nearly blank (a heading or a page number, 13 to 24 characters each). The plan from the previous post was to treat pages where both engines agree as "probably accurate" and hand-check only the rest. On real content pages that agreement almost never happens, so cross-engine agreement doesn't work as the cheap accuracy filter I hoped for.
What the comparison script does
The diff is a single standard-library script, compare_consensus.py, in the soviet.recipes repository. It scans each engine's text/ output folder, matches the two runs by page key (pages-NNN-a and so on), normalizes each transcription (lowercase, strip Docling image tags and markdown punctuation, collapse whitespace), and scores every page two ways:
- Character similarity: Python's
difflib.SequenceMatcherratio over the two normalized strings. Sensitive to reordering and per-character OCR noise. - Word-set Jaccard: size of the shared word set divided by the union. Order-independent, so it measures content overlap even when the two engines lay the page out differently.
Real page content is Cyrillic, so a transcription with almost no Cyrillic is treated as blank (an empty EasyOCR file or a VLM "empty page" caption). Each page lands in one of four buckets:
| Status | Meaning | Count |
|---|---|---|
| MATCH | Both engines produced identical normalized text | 5 |
| MISMATCH | Both have text but it differs | 380 |
| MISSING | One engine found text, the other was blank | 30 |
| BLANK | Neither found real text (photo-only or empty page) | 29 |
The 5 MATCH pages carrying 24 characters indicates a major disagreement. Agreement between two independently-run engines only happened where there was almost nothing to read.
How far apart the transcriptions are
Across the 380 MISMATCH pages, the two similarity scores tell different stories:
| Metric | Mean | Median |
|---|---|---|
| Character similarity | 0.16 | 0.13 |
| Word-set Jaccard | 0.37 | 0.38 |
Character similarity sits near 0.13 while word overlap sits near 0.38. The two engines are reading the same words on a page, but EasyOCR mangles the characters inside those words and scrambles the reading order, so the character sequences diverge far more than the word sets do. Word-level overlap clusters in the middle: of the 380 mismatched pages, 179 fall between 0.2 and 0.4 Jaccard and 154 between 0.4 and 0.6. None reach 0.8.
Where EasyOCR breaks the text
EasyOCR drops and swaps characters inside words, producing strings that aren't real Russian, and it mixes stray Latin letters into Cyrillic text where it misreads a letter shape. Counting Latin characters embedded in the Cyrillic output makes the gap concrete: EasyOCR averages 23.7 stray Latin characters per 1,000 Cyrillic characters and shows them on 366 of 444 pages. Qwen3-VL averages 2.5 per 1,000 across 23 pages, roughly a tenth as much.
Page 82-a (the opening of a chapter titled "В РЫБНОМ МАГАЗИНЕ", "At the Fish Store") is a clean side-by-side because both engines read it top to bottom.
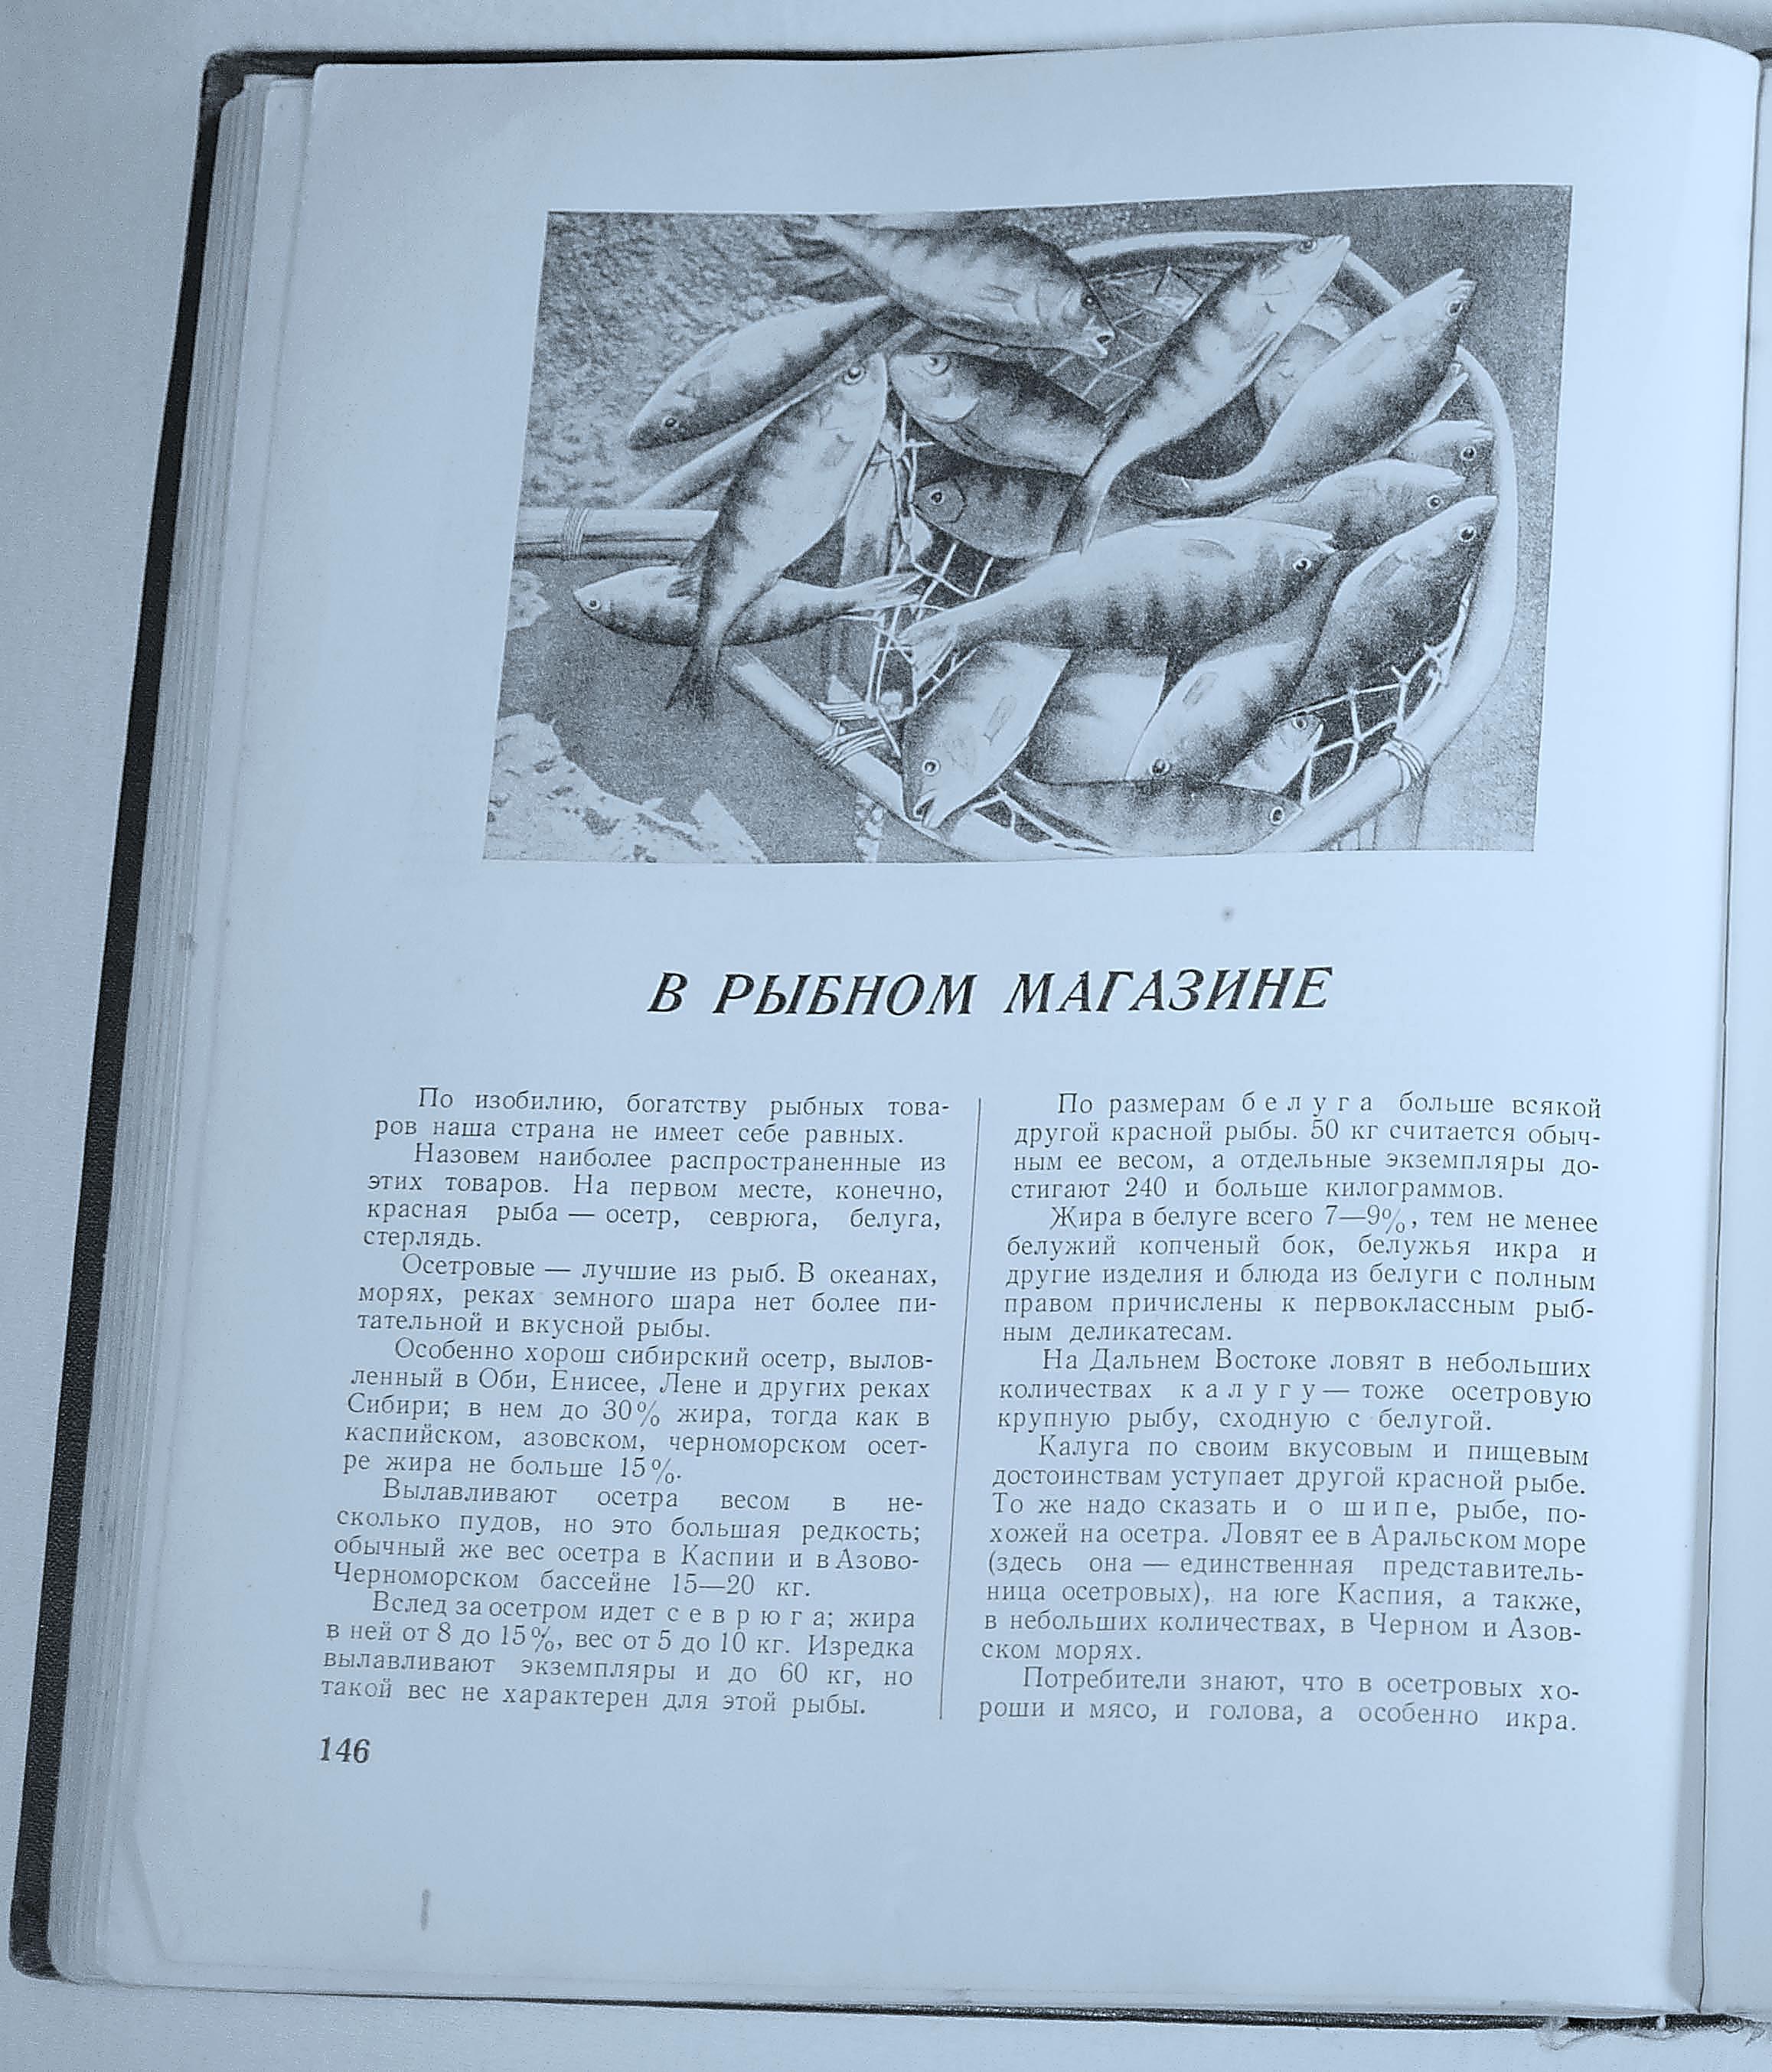
EasyOCR:
## B РЫБНОМ МАГАЗИНЕ

По изобилию, богатству рыбных ров не

тованаша страна имеет себе равных.
Qwen3-VL on the same page:
# В РЫБНОМ МАГАЗИНЕ

По изобилию, богатству рыбных товаров наша страна не имеет
себе равных. Назовем наиболее распространенные из этих товаров.
The heading's first letter comes through as a Latin B instead of Cyrillic В. "товаров" collapses into the fragment "ров", and "товаров наша" merges into the non-word "тованаша". Further down the same page EasyOCR writes "осетpe" with a Latin p and drops "Ha" (Latin) where the text should read "На". This is the pattern the word-set Jaccard picks up as partial overlap while the character similarity reads it as almost total disagreement.
Qwen3-VL also reads more of each page. Setting aside 17 pages where it degenerates (below), and counting only real Cyrillic characters, Qwen3-VL transcribes a median of about 2,490 characters per page against EasyOCR's 1,491. On the pages I checked by hand, the extra text is real content that EasyOCR fragmented or skipped, not invented material.
Where Qwen3-VL breaks instead
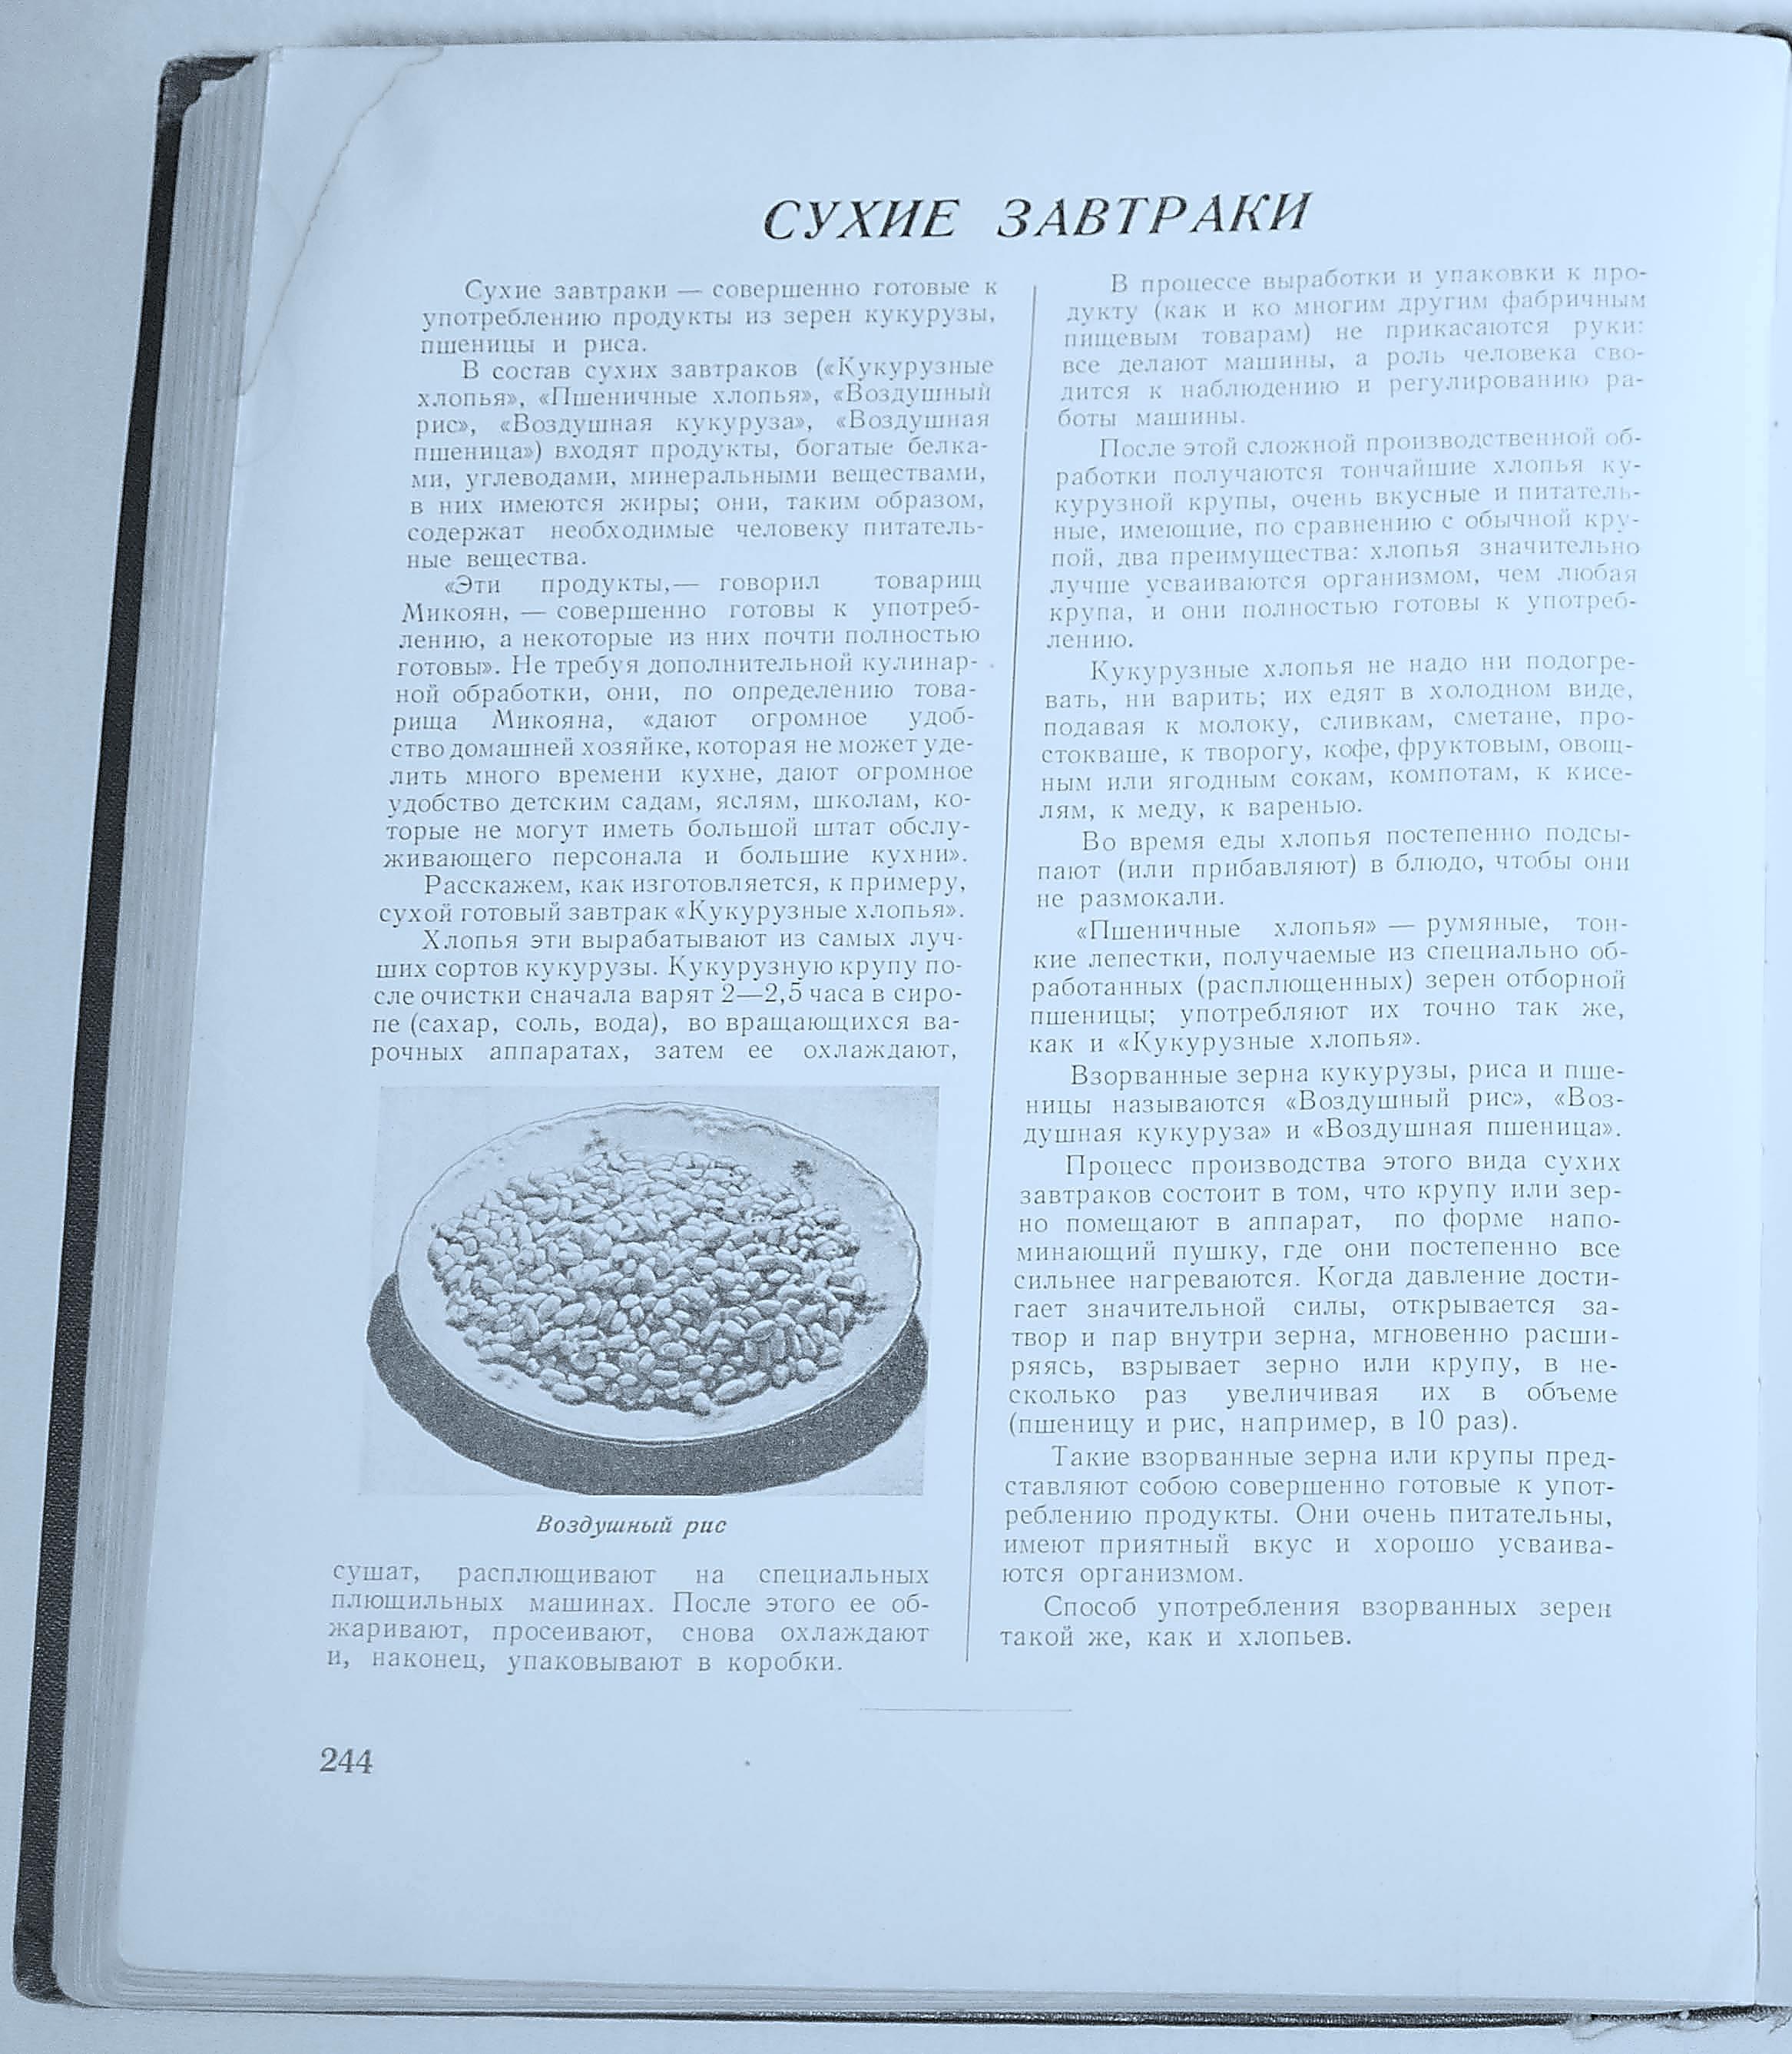
The VLM is not uniformly ahead. Two pages produced no output at all (the 2 failures from the earlier run, pages 137-a and 181-b), and EasyOCR read both. Both are ordinary text pages that EasyOCR transcribed without trouble, so the blank Qwen3-VL results are pipeline failures rather than unreadable pages. Page 137-a is prose about dry breakfast cereals:
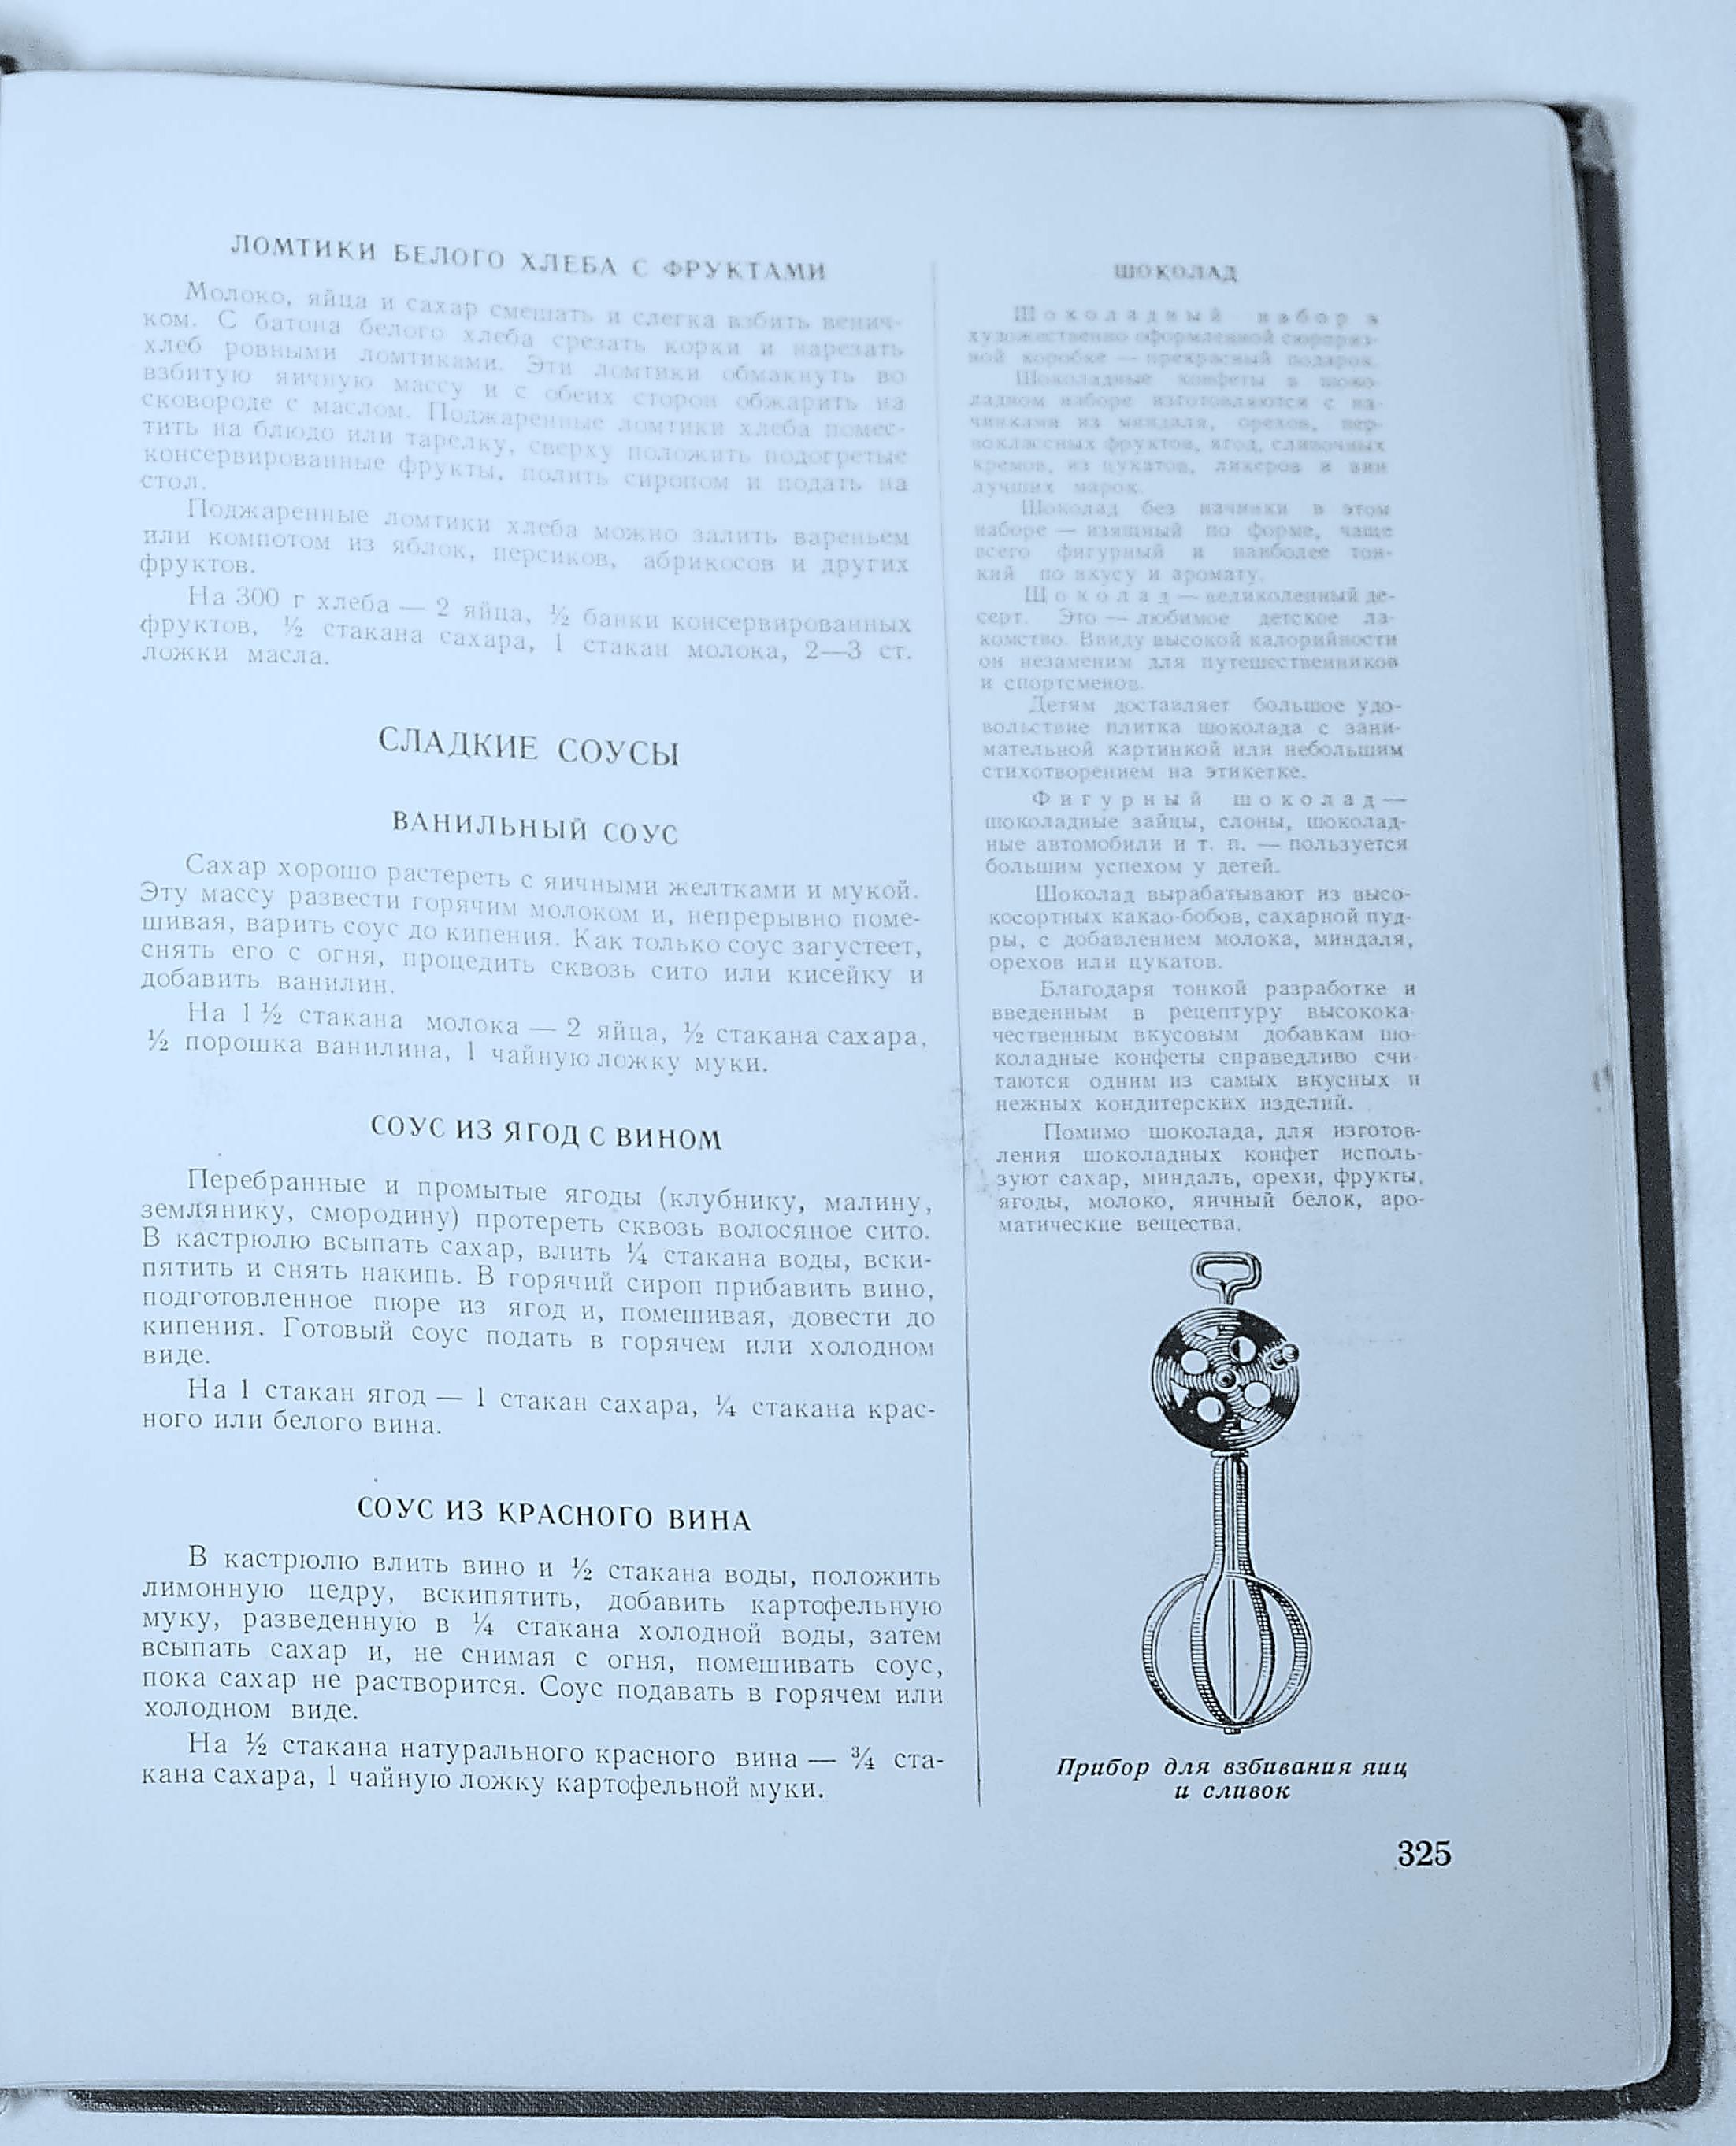
Page 181-b is a page of sweet-sauce recipes with one illustration, and EasyOCR pulled several recipes off it:
The bigger failure is the cookbook's index. On 17 pages, all of them contents or index pages built from dotted leader lines ("Кабачки жареные . . . . . . . . 234"), Qwen3-VL loses the plot and emits a runaway string of . . . . . until it hits its generation limit, filling each file with about 57,600 characters of dots wrapped in a code fence. EasyOCR never does this; on those same pages it returns fragmentary but real entries with their page numbers. The repetitive visual pattern that a VLM has to generate token by token is exactly where the region-based engine holds up better.
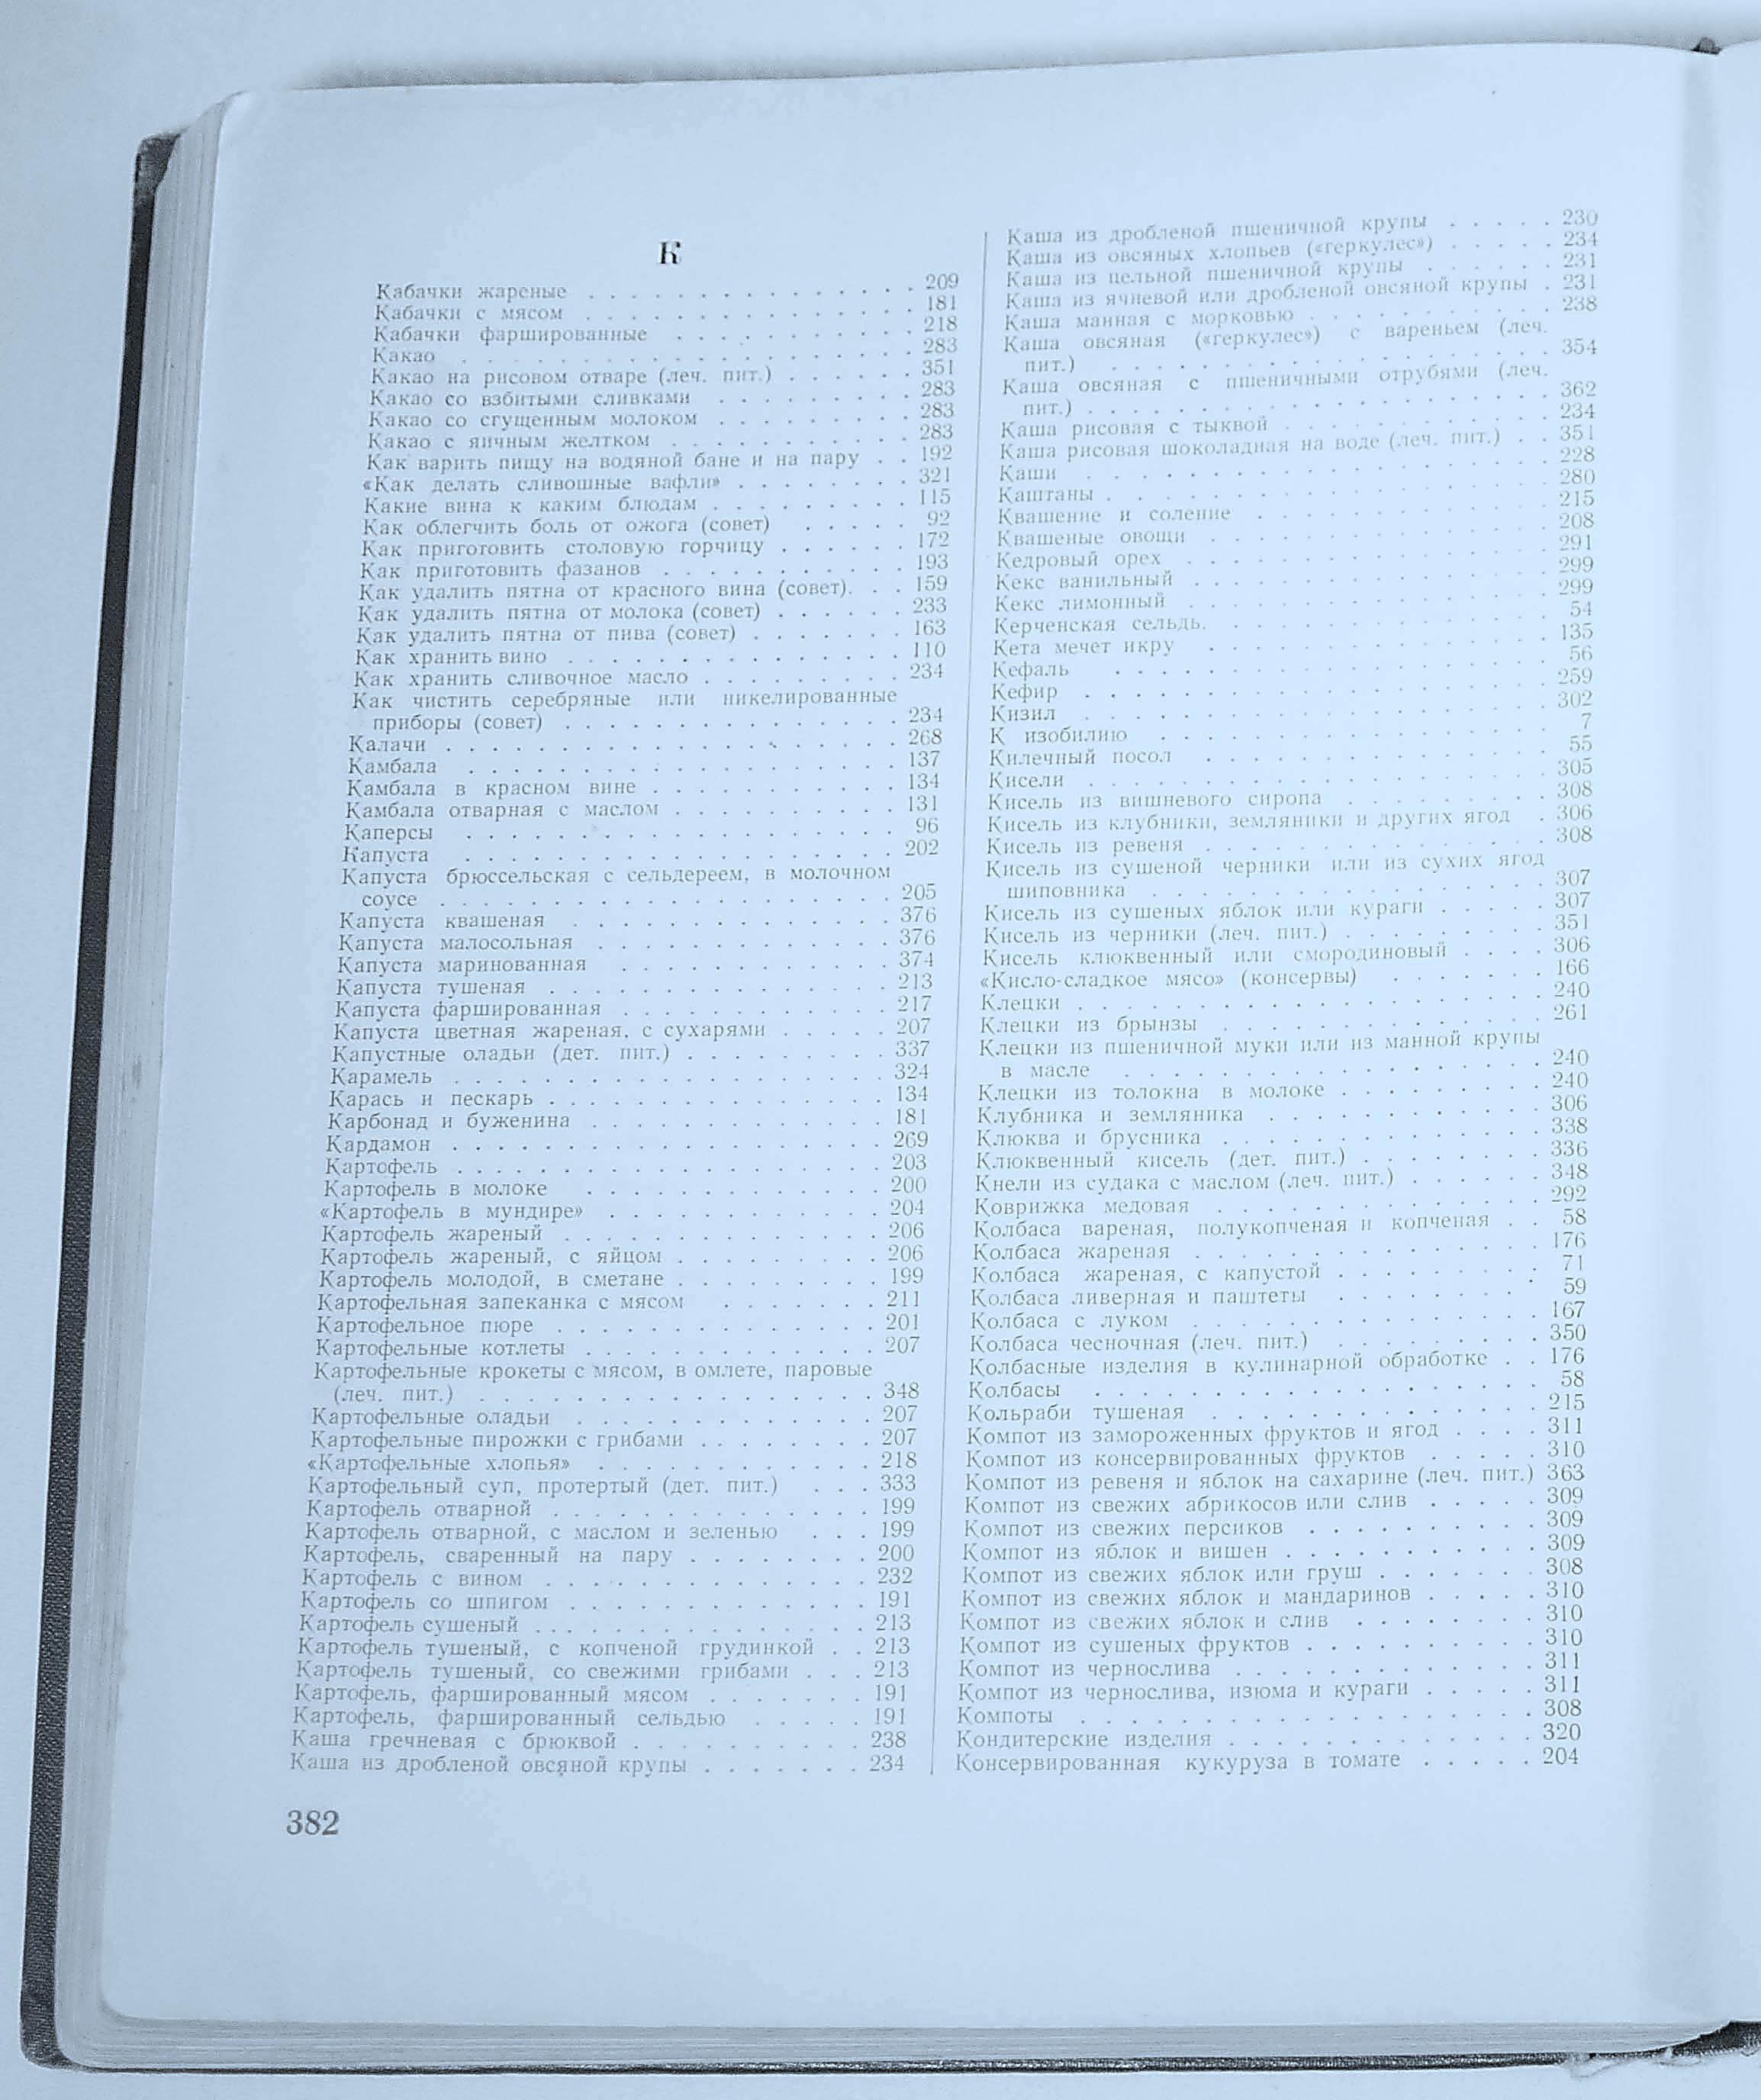
Those 17 pages are why the raw character totals need care. Counted naively, Qwen3-VL looks like it produced 2.6 times more text than EasyOCR, but roughly half of that volume is dot-loop garbage from the index pages. The median-per-page figure above excludes them.
What this means for the pipeline
Cross-engine agreement was supposed to be the cheap accuracy signal: where two independently-run engines produce the same text, trust it, and spend the hand-checking budget on the rest. With exact agreement landing on only 5 near-blank pages, that filter selects almost nothing on real content.
Word-set Jaccard is the more useful output of the diff than the MATCH flag. A page where the two engines share most of their words is a page where they read the same recipe and disagree on spelling and layout, which is a reasonable place to prefer the cleaner Qwen3-VL transcription. A page with near-zero word overlap is where something went wrong for at least one engine, and those are worth looking at directly, whether it's an EasyOCR blank or a Qwen3-VL dot-loop.
The next thing worth trying is the DocTags-native VLM swap the previous post floated (SmolDocling or Granite-Docling). Real bounding boxes would let the diff align text region by region instead of comparing two flat blobs, which would separate genuine misreads from layout noise and give the word-overlap score something firmer to stand on.
This work is part of the soviet.recipes project. See the phase 2 planning post, the EasyOCR proof-of-concept, the batch-processing pipeline post, and the Qwen3-VL vs EasyOCR run for the earlier steps, and the soviet-recipes-project tag for everything related.